Iceberg Table Layout: Avro Metadata And Parquet Data Files
If you look inside an Iceberg table directory and see .avro files under
metadata/, it is easy to assume the table data is Avro. It usually is not.
Iceberg is the table format. Parquet, ORC, and Avro are file formats that an Iceberg table can point to. In a common Trino lakehouse table, Iceberg metadata uses JSON and Avro files, while the actual table rows live in Parquet files. This post walks through one small table to keep those roles apart:
metadata/*.json:
  Iceberg table metadata

metadata/*.avro:
  Iceberg snapshot and manifest metadata

data/*.parquet:
  actual table rows
1. The Small Example
We start with an Iceberg table written as Parquet:
CREATE TABLE iceberg.tpch.orders
WITH (
    format = 'PARQUET',
    partitioning = ARRAY['o_orderstatus']
) AS
SELECT *
FROM tpch.tiny.orders;
The table name is:
iceberg.tpch.orderswhich breaks down as:
catalog:
  iceberg

schema:
  tpch

table:
  orders
The catalog routes access to the Iceberg connector. The table property
format = 'PARQUET' says the table’s data files should be Parquet. It does not
mean every file under the table directory is Parquet.
A simplified table directory can look like this:
orders/
  metadata/
    00000.metadata.json
    00001.metadata.json
    snap-1001.avro
    manifest-a.avro
    manifest-b.avro

  data/
    o_orderstatus=F/file_001.parquet
    o_orderstatus=O/file_002.parquet
    o_orderstatus=P/file_003.parquet
The two directories have different purposes:
metadata/:
  how Iceberg knows which files belong to the table

data/:
  where the row data is stored
Avro under metadata/ does not mean the table rows are Avro. It means Iceberg
is using Avro for manifest metadata.
2. The Metadata Chain
An Iceberg read does not scan every file under the table directory and guess which ones are current. It starts from a metadata pointer and walks a snapshot chain:
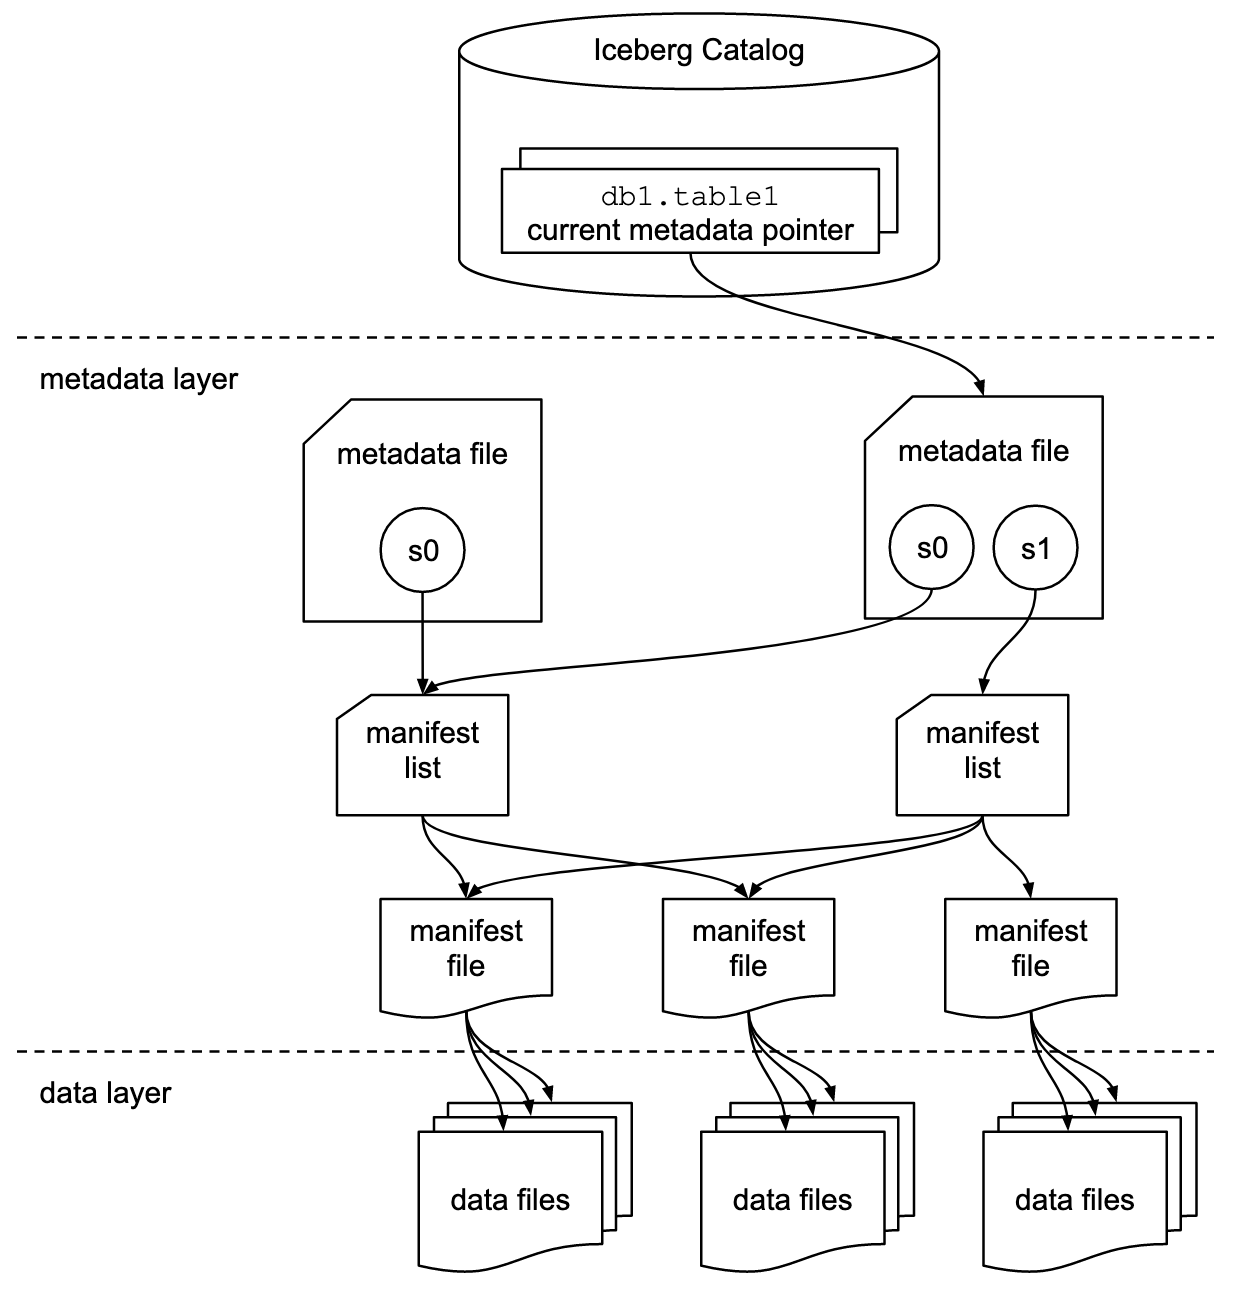
catalog
  -> current metadata.json
    -> current snapshot
      -> manifest list
        -> manifest file
          -> data file
Each layer has a separate job:
| Layer | Typical file | Job |
|---|---|---|
| Catalog pointer | metastore, REST catalog, or another catalog backend | Points to the current Iceberg metadata file. |
| Table metadata | metadata/00001.metadata.json |
Stores schema, partition specs, table properties, snapshots, and current snapshot id. |
| Manifest list | metadata/snap-1001.avro |
Lists the manifest files used by one snapshot. |
| Manifest file | metadata/manifest-a.avro |
Lists data files, partition values, record counts, and file-level metrics. |
| Data file | data/.../*.parquet |
Stores actual table rows. |
This chain is what makes snapshots and time travel possible. A query reads the files for one selected snapshot, not every file that happens to still exist in the table directory.
3. Metadata JSON
The table metadata JSON is the table-level file. It stores facts such as:
schema
partition specs
table properties
snapshot history
current snapshot id
metadata file history
The current snapshot id connects table-level metadata to the list of data files that are visible to a query. A simplified example:
00001.metadata.json
  current-snapshot-id: 1001
  snapshots:
    snapshot 1000 -> metadata/snap-1000.avro
    snapshot 1001 -> metadata/snap-1001.avro
The real JSON has more detail, but this is the order I read it in:
metadata.json chooses the snapshot.
The snapshot points to manifest metadata.
Manifest metadata points to data files.
4. Manifest List vs Manifest File
The two Avro metadata layers are easy to blur together.
A manifest list is snapshot-level metadata. It tells Iceberg which manifest files belong to a snapshot. For our table:
snap-1001.avro

contains:
  manifest-a.avro
    partition summary: o_orderstatus = F
    added files: 2

  manifest-b.avro
    partition summary: o_orderstatus = O
    added files: 1
A manifest file is data-file metadata. It lists actual data files along with facts that can help pruning:
manifest-a.avro

contains:
  data/o_orderstatus=F/file_001.parquet
    file_format: PARQUET
    partition: o_orderstatus = F
    record_count: 5000
    lower_bounds:
      o_totalprice = 120.50
    upper_bounds:
      o_totalprice = 9500.00

  data/o_orderstatus=F/file_002.parquet
    file_format: PARQUET
    partition: o_orderstatus = F
    record_count: 4000
    lower_bounds:
      o_totalprice = 10.00
    upper_bounds:
      o_totalprice = 800.00
In short:
manifest list:
  snapshot -> manifest files

manifest file:
  manifest -> data files
5. Why There Are Multiple Metadata Files
Iceberg tables are snapshot-based. A write does not mutate one metadata file in place. It writes new metadata and then updates the catalog pointer:
metadata/00000.metadata.json  -- table created
metadata/00001.metadata.json  -- first insert
metadata/00002.metadata.json  -- later insert, delete, or schema change
Old metadata files can remain because Iceberg supports:
time travel
rollback
snapshot history
concurrent commits
audit and debugging
Cleanup is a separate maintenance task. Old metadata and orphan files are not removed just because a newer snapshot exists.
6. Why The Metadata Is Avro
Iceberg core metadata commonly uses:
JSON:
  table-level metadata

Avro:
  manifest lists and manifest files
The table data uses whichever data-file format is configured:
PARQUET
ORC
AVRO
So this layout is normal:
metadata/snap-1001.avro
metadata/manifest-a.avro
data/file_001.parquet
The .avro files are metadata, and the .parquet file is row data.
Avro can also be used as a data-file format, but that is a separate choice:
metadata/manifest-a.avro:
  Iceberg metadata

data/file_001.avro:
  table rows, only if the table data format is AVRO
Putting the formats side by side:
| Format | Iceberg core metadata? | Iceberg table data? |
|---|---|---|
| JSON | Yes, table metadata | No |
| Avro | Yes, manifest lists and manifests | Yes, if table data format is AVRO |
| Parquet | Not normally for core metadata | Yes, common for analytics |
| ORC | Not normally for core metadata | Yes |
7. How This Helps Query Pruning
Consider this query:
SELECT *
FROM iceberg.tpch.orders
WHERE o_orderstatus = 'F'
  AND o_totalprice > 1000;
Iceberg can use metadata to rule out files before opening any of them. At the manifest-list layer:
skip manifests that only contain o_orderstatus = O
keep manifests that may contain o_orderstatus = F
At the manifest-file layer:
skip file_002.parquet because max(o_totalprice) = 800
keep file_001.parquet because max(o_totalprice) = 9500
That is Iceberg metadata pruning, and it is not the same as Parquet row-group pruning. The layers are:
Iceberg metadata:
  skip whole manifests or whole data files

Parquet metadata:
  skip row groups, column chunks, or pages inside a selected Parquet file

Trino engine:
  still evaluates any predicate that the connector cannot fully guarantee
This distinction comes up again in later posts. When EXPLAIN shows a pushed
constraint, that does not automatically mean the connector fully filtered every
row by itself. It may mean the connector used metadata for pruning while Trino
still kept a remaining filter for correctness.
8. Why Parquet Is Usually The Data Format
For Trino analytics, Parquet is usually a better Iceberg data-file format than Avro. Parquet is columnar, which lets the reader:
read useful columns
skip impossible row groups
use column statistics
decode batches into Trino blocks and pages
Avro is row-oriented:
good for serialization and event-style records
less useful for analytical column pruning
usually fewer inner-file pruning opportunities
Choosing Parquet does not change the metadata. The manifests are still Iceberg metadata, commonly Avro. The benefit comes after Iceberg selects candidate data files: the Parquet reader then has a columnar file layout and richer internal metadata to work with.
The rule I follow:
Use Parquet as the default for Iceberg tables queried by Trino.
Use ORC if the lakehouse stack is already optimized around ORC.
Use Avro data files only for a specific compatibility or write-path reason.
9. Trino Inspection Queries
These queries are the quickest way to check all of this from Trino.
Table properties, including the data-file format:
SELECT *
FROM iceberg.tpch."orders$properties";
Metadata JSON history:
SELECT *
FROM iceberg.tpch."orders$metadata_log_entries"
ORDER BY timestamp DESC;
Snapshots and their manifest-list Avro files:
SELECT snapshot_id, manifest_list
FROM iceberg.tpch."orders$snapshots";
Manifest files:
SELECT *
FROM iceberg.tpch."orders$manifests";
Actual data files and their formats:
SELECT file_path, file_format, record_count, lower_bounds, upper_bounds
FROM iceberg.tpch."orders$files";
The check I want to be able to make quickly:
metadata/*.avro:
  Iceberg manifests

orders$files.file_format:
  actual table data format
10. Going forward
The next post goes deeper into Parquet itself:
row groups
column chunks
Parquet pages
encoding
compression
footer statistics
After that, the read-trace post connects the layers:
SQL
  -> Iceberg table handle
  -> Iceberg metadata pruning
  -> IcebergSplit
  -> Parquet reader
  -> Trino Page
11. What To Remember
Iceberg is a table format, not a data-file encoding; Parquet, ORC, and Avro are
the data-file formats it can reference. A read starts from a catalog pointer
and a metadata JSON file, which selects a snapshot. The snapshot points to a
manifest-list Avro file, and manifest files list the data files along with
file-level metrics. That is why .avro files under metadata/ say nothing
about the format of the table rows.
For Trino analytics, Parquet is usually the practical default data format. Iceberg metadata pruning and Parquet row-group/page pruning are separate layers, and the engine may still apply a remaining filter on top of both.
12. Self-Check
Questions to answer without looking back:
- What is the difference between Iceberg and Parquet?
- Why can an Iceberg table with Parquet data files still have Avro files under
metadata/? - What does
metadata.jsonpoint to? - What is the difference between a manifest list and a manifest file?
- Which layer points to actual data files?
- Where would I check the actual data-file format from Trino?
- Why does Iceberg keep multiple metadata JSON files?
- What can Iceberg metadata prune before opening a Parquet file?
- Why is Iceberg metadata pruning different from Parquet row-group pruning?
13. References
- Trino Iceberg connector
- Apache Iceberg table specification
- Apache Parquet concepts