Spark Join Strategies: Five Common Joins with a Runnable Local Lab
DataFrame.join() describes a logical relationship between two inputs. The
physical join strategy is how Spark actually makes the two sides meet: by
copying a small relation to every executor, repartitioning both sides, sorting
them, or comparing every possible pair.
This post walks through five common strategies. For each one we look at how data moves between executors, a minimal PySpark example, and what the Spark UI shows when it runs. The companion Docker standalone lab is in: https://github.com/zivali/spark-join-strategies-lab, which generates deterministic 10M and 100M-row datasets and saves the observed plan and runtime data.
- Broadcast Hash Join
- Shuffle Hash Join
- Sort-Merge Join
- Cartesian Join
- Broadcast Nested Loop Join
The overview below summarizes all five. Each strategy section then ties together the diagram, the code, and the physical operator. The results at the end compare only the three strategies that share the same equality-join inputs; the Cartesian and Broadcast Nested Loop examples use deliberately bounded workloads.
1. Strategy at a glance
| Strategy | Typical condition | Main data movement | Good fit | Main danger |
|---|---|---|---|---|
| Broadcast Hash Join | Equality | Small side copied to each executor | One genuinely small side | Executor memory pressure / over-broadcasting |
| Shuffle Hash Join | Equality | Both sides shuffled by key; one side hashed per partition | Hashable, partition-local build side | Per-partition hash table too large |
| Sort-Merge Join | Equality | Both sides shuffled and sorted by key | Large inputs; stable default | Expensive shuffle and sorting |
| Cartesian Join | No join predicate | Every left row paired with every right row | Deliberate all-pairs analysis | Output grows as left_rows × right_rows |
| Broadcast Nested Loop Join | Usually non-equality | Small side broadcast; every candidate compared | A small side plus non-equi predicate | Quadratic-like comparison work |
1.1. Default selection without hints
For a typical equality join with no hints or custom configuration, Spark usually decides as follows:
- Try Broadcast Hash Join if it estimates one side is small enough to
broadcast. The default
spark.sql.autoBroadcastJoinThresholdis 10 MiB. - Otherwise, use Sort-Merge Join for large equality inputs in many cases,
because
spark.sql.join.preferSortMergeJoindefaults totrue. - Spark can choose Shuffle Hash Join when it determines a build side fits per shuffle partition, but this is not the usual default preference.
This is a rule of thumb, not a guarantee. Table statistics, join type, key
distribution, Spark version and configuration, and Adaptive Query Execution
(AQE) can all lead to a different physical operator. Check the actual choice with
joined.explain("formatted").
2. The shared input used in the diagrams
The equality-join diagrams all use this input:
fact partition |
Fact row | products row |
|---|---|---|
| 1 | (order=101, product_id=101, amount=12) |
(product_id=101, name=product-101) |
| 2 | (order=102, product_id=102, amount=30) |
(product_id=102, name=product-102) |
For equality joins, product_id is the key. The output is:
(101, 101, 12, product-101)
(102, 102, 30, product-102)
An equality join (or equi-join) matches rows where one or more join keys are
equal, for example fact.product_id = products.product_id. Broadcast Hash Join,
Shuffle Hash Join, and Sort-Merge Join are the usual physical strategies for
this kind of condition. A predicate such as fact.metric < customer.tier_limit
is a non-equi join, so it cannot use a hash lookup on a single equality key.
In the local lab, fact is the large relation at 10M or 100M rows.
customers has 1M rows and products has 10K rows.
3. Broadcast Hash Join
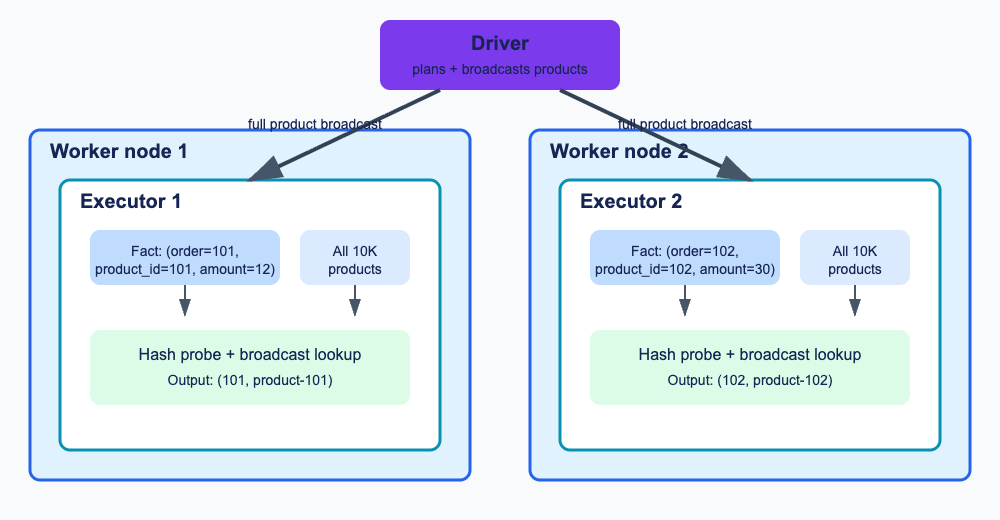
Spark copies the 10K-row products side to every executor. Each executor builds
an in-memory hash map from those rows and probes it with its local fact
partition. The large fact side needs no join shuffle; Spark simply distributes
its partitions across executor tasks.
In the diagram, the small blue box stands for the entire products relation
(all 10K rows), which is available on each executor. product_id=101 and
product_id=102 are just the fact rows being probed in this example.
3.1. Reading the diagram
Since this is the first diagram, here is what each part means. The purple Driver plans the physical join, schedules tasks, and initiates the product broadcast; it does not scan every row. Each light-blue Worker node contains an Executor, which reads its assigned fact partition and does the row-level work. The blue blocks are input data: a larger fact partition and the full, smaller product relation copied to that executor. The green block is the executor-local hash lookup and joined output. Because the products are broadcast, the large fact side never has to be shuffled for the join.
Use it when one side is comfortably small after serialization, and copying it once per executor is cheaper than shuffling the large side. A table that is small on disk may still be too large once decoded into JVM objects, so measure executor memory and broadcast time.
Minimal PySpark shape:
from pyspark.sql import functions as F

joined = fact.join(F.broadcast(products), "product_id")
joined.explain("formatted")
The expected plan operator is BroadcastHashJoin. The companion lab README has
the reproducible command and report workflow.
3.2. Observed local 10M run
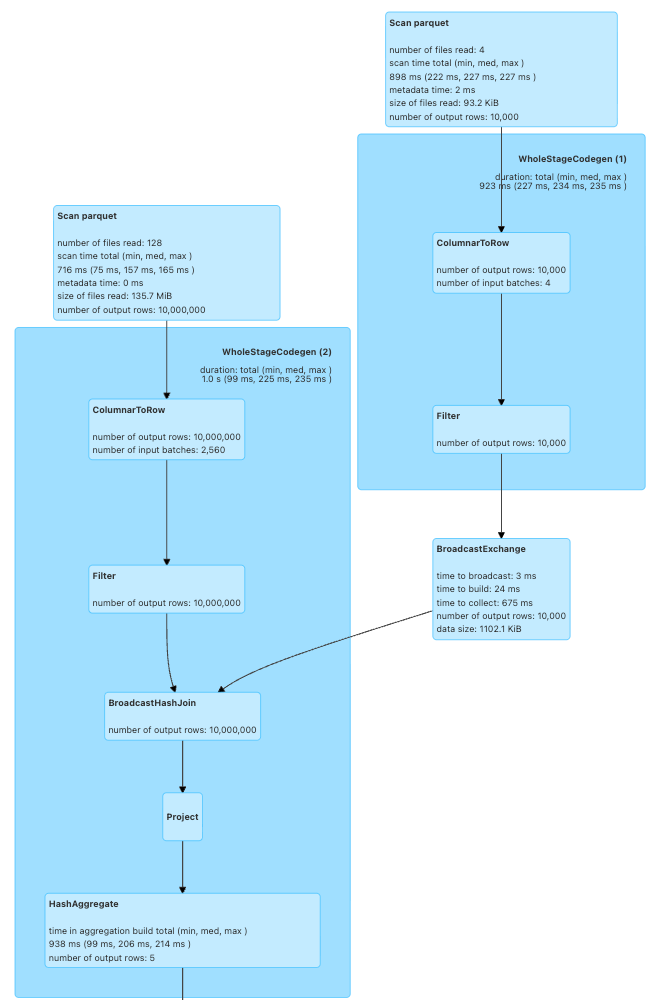
The Spark UI shows BroadcastHashJoin producing a 10M-row result in
1.493 seconds. The 10K-row product side is scanned once, then
BroadcastExchange builds a 1,102.1 KiB broadcast relation, and the 10M-row
fact side feeds directly into BroadcastHashJoin. There is no large fact-side
join exchange.
4. Shuffle Hash Join
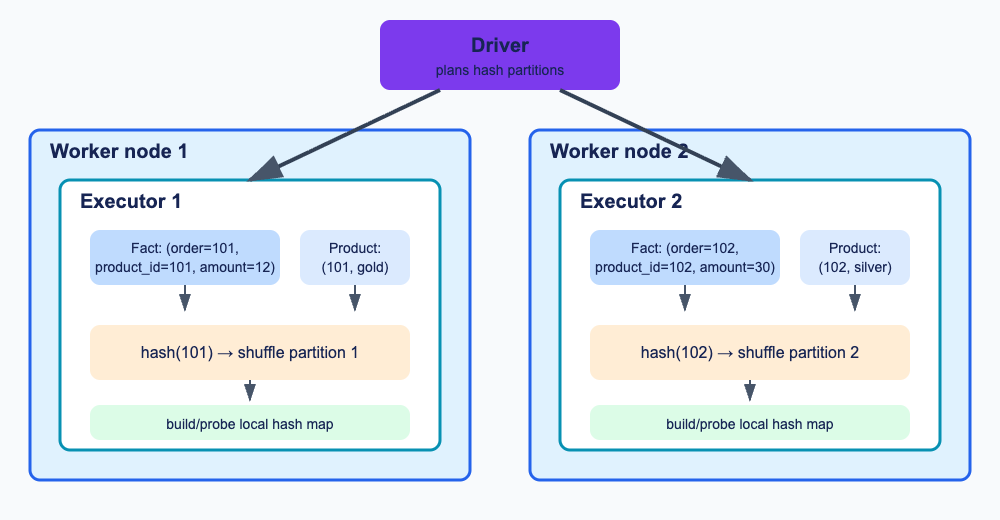
Here Spark hash-partitions both sides on the equality key. Within each resulting partition, it builds a hash table from one side and probes it with the other. Unlike the broadcast case, both relations move across the network.
4.1. How matching keys meet
The driver schedules tasks; it does not send individual product_id values
to executors. Across the cluster, executors read all required source partitions
from both fact and products, but any one executor reads only the partitions
assigned to its current task. The join then happens in two phases:
- Shuffle write: each executor hashes every row it reads and writes it to a
shuffle bucket, for example
hash(product_id) % shuffle_partition_count. - Shuffle read and join: a later task fetches one bucket from both inputs. It therefore receives all fact and product rows for the same hashed key range, builds a partition-local hash table, and probes it.
For example, if product_id=7 hashes to bucket 0 and product_id=9 hashes to
bucket 1, bucket 0 receives the fact and product rows for key 7, while bucket 1
receives both rows for key 9. The scheduler may run either bucket on either
executor. What Spark guarantees is that matching keys from both inputs end up in
the same shuffle bucket before the join.
In the diagram, the new orange blocks mark the shuffle-write boundary
(hash(key) → shuffle partition). The green block appears only after a join
task has fetched the matching bucket from both inputs and builds and probes its
partition-local hash map.
4.2. Where the phases appear in Spark UI
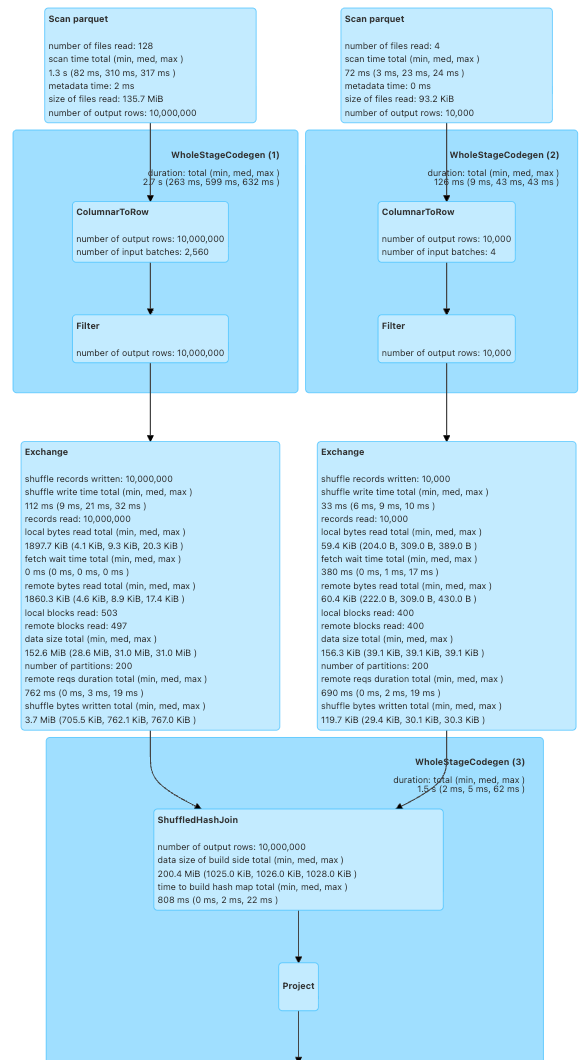
In the DAG, each path shaped like Scan parquet → WholeStageCodegen → Exchange
is the shuffle-write phase. Executor tasks read their assigned source
partitions and hash product_id, and the Exchange boxes report the records
and bytes written to shuffle storage.
Where the two Exchange paths feed ShuffledHashJoin is the shuffle-read and
join phase. A new executor task fetches its matching bucket from both exchanges
(visible as shuffle-read metrics in the stage and task details), then builds and
probes its partition-local hash table. The driver only schedules these tasks; it
does not read, shuffle, or join the rows.
Use it when both inputs need repartitioning but the per-partition build side fits in memory. It avoids the sort, but a skewed key can make one hash partition much larger than the others.
Minimal PySpark shape:
spark.conf.set("spark.sql.autoBroadcastJoinThreshold", -1)
spark.conf.set("spark.sql.join.preferSortMergeJoin", "false")

joined = fact.hint("shuffle_hash").join(
    products.hint("shuffle_hash"), "product_id"
)
joined.explain("formatted")
The expected plan operator is ShuffledHashJoin.
4.3. Observed local 10M run
The Spark UI shows ShuffledHashJoin producing the same 10M-row result in
2.826 seconds. Unlike Broadcast Hash Join, both inputs pass through an
Exchange before the join: in this run the fact-side exchange writes 3.7 MiB
and the product-side exchange writes 119.7 KiB. ShuffledHashJoin then reports
a 200.4 MiB build-side hash-map data size.
5. Sort-Merge Join
Sort-Merge Join partitions both sides by key, sorts each partition by that key, and then walks the two sorted streams together. For large inputs this is often a reliable default, because there is no per-partition hash table to hold for the whole build relation.
In the diagram, the orange block now covers both the shuffle and the sort:
each shuffled bucket is sorted by product_id before the green merge block walks
the two sorted streams together. There is no partition-wide build-side hash map.
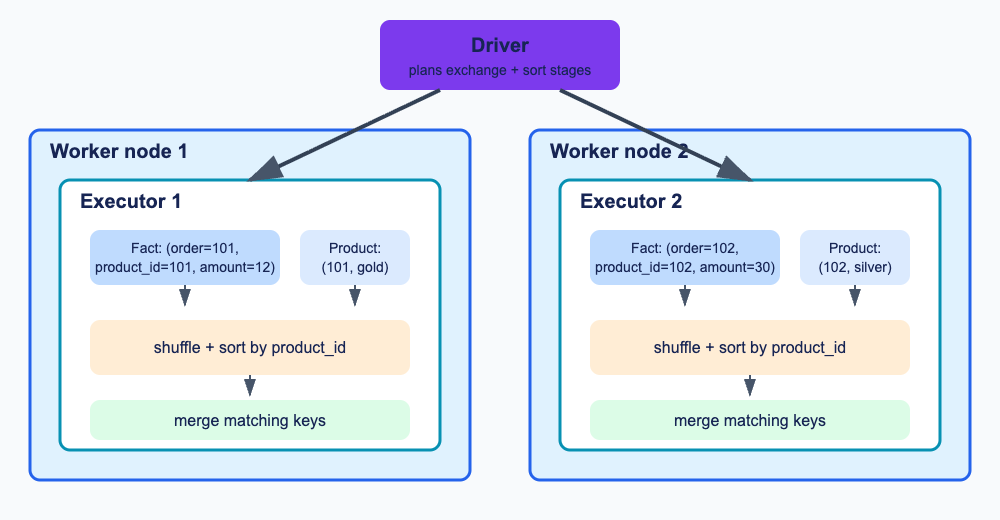
Use it for large equi-joins where neither side is safe to broadcast. The cost is two wide shuffle and sort pipelines. Check spill, disk I/O, and task skew before assuming the sort itself is the only bottleneck.
Minimal PySpark shape:
spark.conf.set("spark.sql.autoBroadcastJoinThreshold", -1)
spark.conf.set("spark.sql.join.preferSortMergeJoin", "true")

joined = fact.hint("merge").join(products.hint("merge"), "product_id")
joined.explain("formatted")
The expected plan operator is SortMergeJoin.
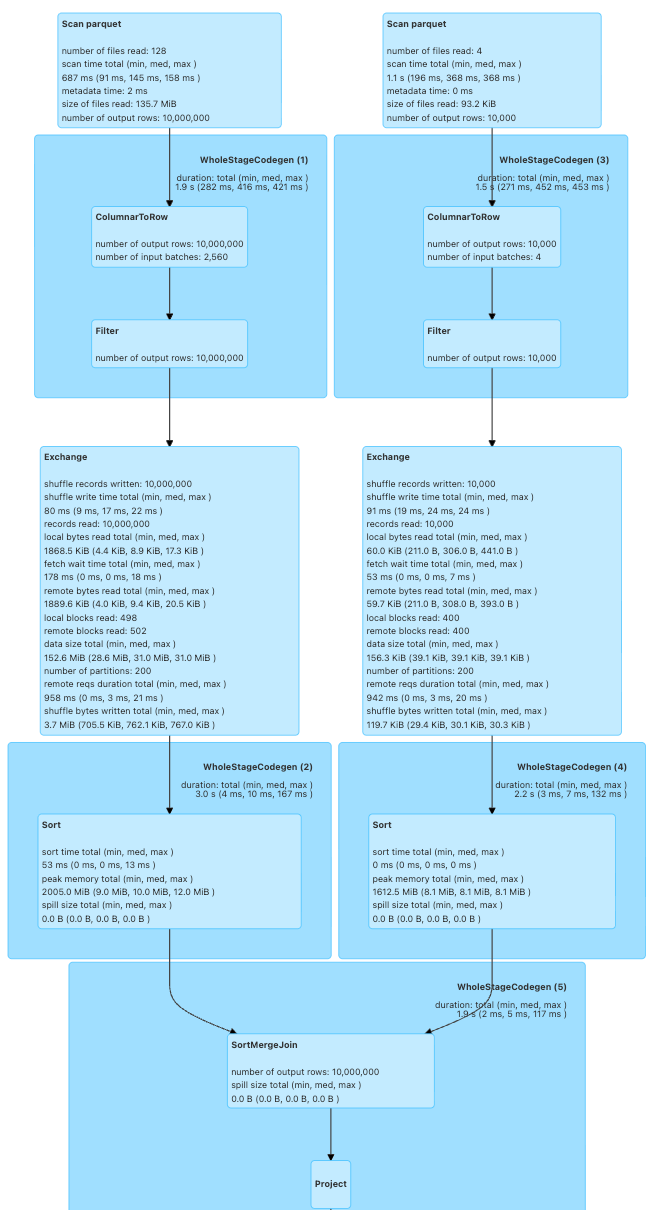
In the Spark UI, look for the exchange and sort stages on both join inputs. Elapsed time is only part of the picture; also compare shuffle bytes, spill, and the p75 versus max task duration.
5.1. Observed local 10M run
The Spark UI shows SortMergeJoin producing the same 10M-row result in
3.467 seconds. Both inputs pass through an Exchange and a Sort before
the merge: the fact-side exchange writes 3.7 MiB, and the 10K-product
side writes 119.7 KiB. This run reports 0 B of spill at SortMergeJoin.
5.2. Shuffle Hash Join vs. Sort-Merge Join
Both strategies first shuffle fact and products so that matching
product_id values land in the same partition. A shuffle partition is a bucket
holding many key values, not one partition per key. For example:
hash(7)  → partition 0
hash(19) → partition 0
hash(9)  → partition 1
The difference is in the local work done inside each shuffled partition:
| Local work inside one shuffled partition | Shuffle Hash Join | Sort-Merge Join |
|---|---|---|
| Preparation | Build one hash map, usually from the smaller side | Sort both sides by the join key |
| Match rows | Stream/probe the other side against that map | Advance cursors through both sorted streams |
| Main trade-off | Hash-map memory per partition | Shuffle plus sort work; no full build-side hash map |
For a bucket containing product IDs 7 and 19, Shuffle Hash Join can build:
products hash map: 7 → product-7, 19 → product-19
fact probe rows:    7, 19
Sort-Merge Join instead sorts both local streams and compares their current keys:
fact rows:     7, 7, 19, 19, 25
product rows:  7,    19,     25
When the cursors reach equal keys, Spark emits the matching group and advances. Two fact rows with key 7 and one product row with key 7 therefore produce two joined rows. Neither strategy pins a key to a particular executor: the driver schedules a task for a shuffle partition, and any executor can process it.
6. Cartesian Join
A Cartesian join pairs every row on the left with every row on the right. It is only useful when you actually want all pairs. A join condition left out by mistake can blow up the row count very quickly.
The new red block in the diagram represents pairwise work: every left row is
paired with every right row. The yellow block shows the resulting pairs, whose
count grows as left_rows × right_rows.
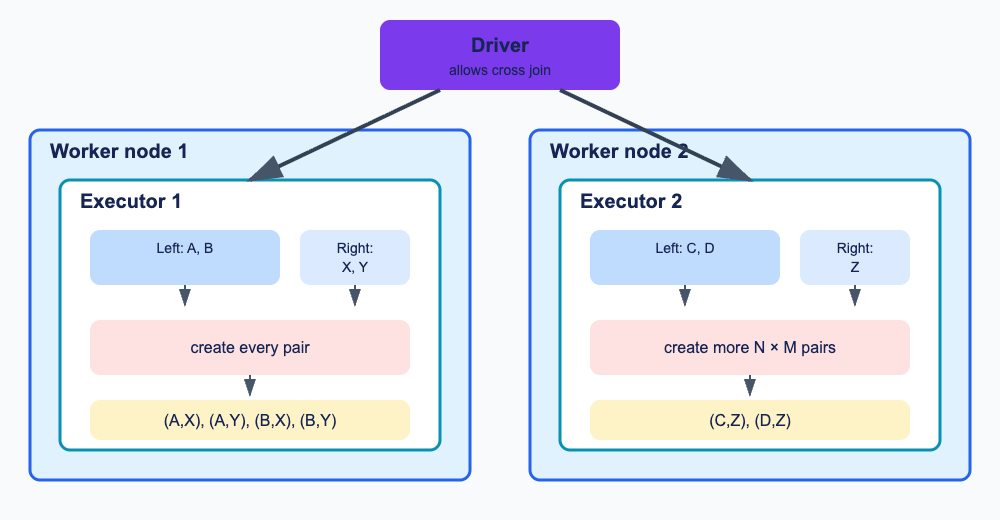
Two input rows on each side produce four pairs. At scale, 10M rows by 100 rows is already 1B candidates, so the lab deliberately bounds this example to 10,000 fact rows and 100 product rows (1M pairs), even when you select the 10M or 100M dataset.
Minimal PySpark shape:
spark.conf.set("spark.sql.crossJoin.enabled", "true")

joined = fact.limit(10_000).crossJoin(products.limit(100))
joined.explain("formatted")
The expected plan operator is CartesianProduct.
If this operator shows up unexpectedly in a production plan, check the logical
join condition before tuning executors. No amount of capacity makes an
unintended N × M output safe.
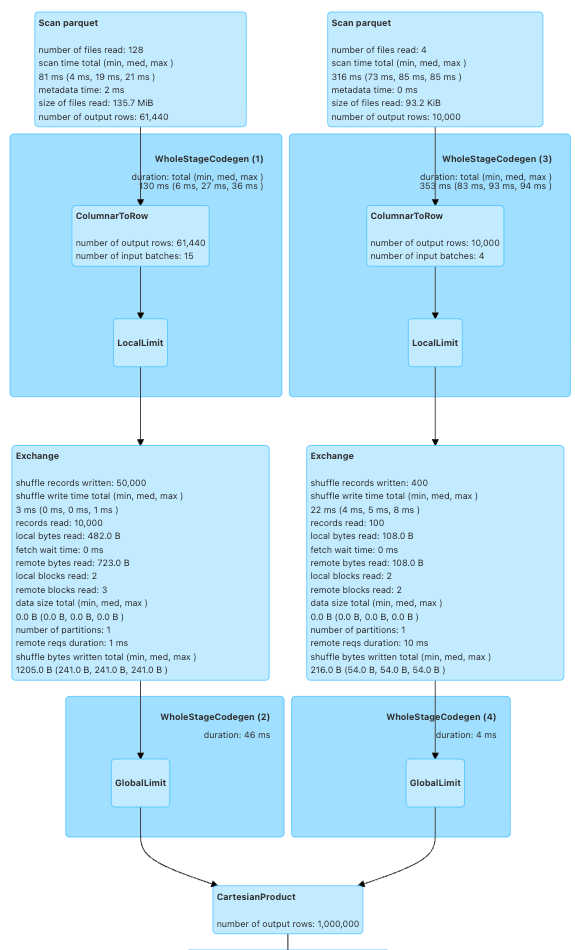
6.1. Observed local 10M run
The Spark UI shows CartesianProduct producing a 1M-row result in
1.094 seconds. This is not a full 10M-by-10K cross product: the plan applies
LocalLimit and GlobalLimit first, keeping 10,000 fact rows and 100 product
rows before creating every pair. The two exchanges in the DAG coordinate those
global limits; they are not hash-partitioning on a join key.
7. Broadcast Nested Loop Join
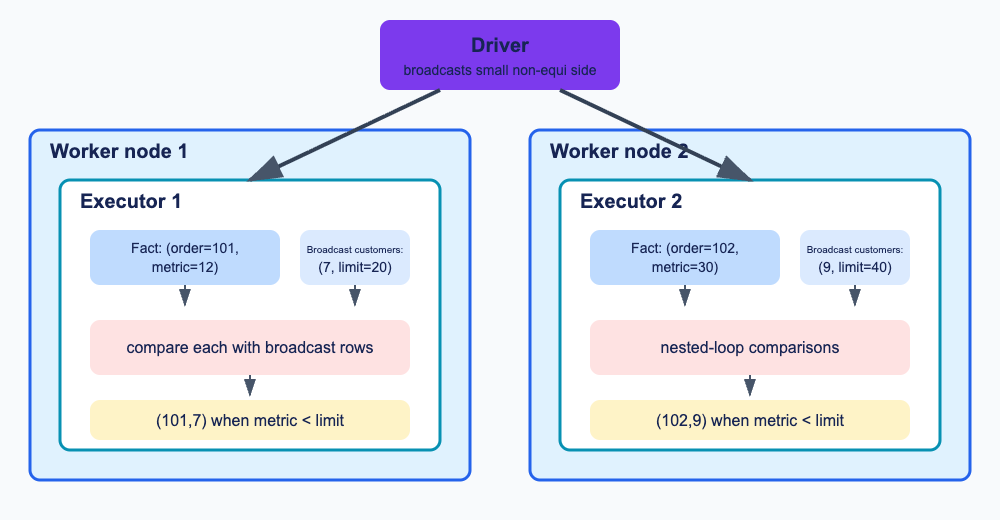
Broadcast Nested Loop Join broadcasts a small side, then compares every local
left row with every broadcast row. It is needed when the condition has no
hashable equality key: for fact.metric < customer.tier_limit, Spark cannot
look up a single matching key.
The diagram reuses the red pairwise-work block, but this time the small right
side is broadcast first. Each executor compares every local fact row with the
broadcast threshold rows, because the < predicate offers no equality key for a
hash lookup.
Use it only when the broadcast side is truly small and there is no equi-key for a better join. The lab restricts the non-equi example to 10,000 fact rows and 100 customer rows, again to keep the number of comparisons bounded.
Minimal PySpark shape:
from pyspark.sql import functions as F

small_customers = customers.filter("customer_id < 100")
joined = fact.limit(10_000).join(
    F.broadcast(small_customers),
    fact.metric < small_customers.tier_limit,
    "inner",
)
joined.explain("formatted")
The expected plan operator is BroadcastNestedLoopJoin.
For a non-equi join, first see whether you can pre-filter, bucket or range-prune, or reformulate the problem as an equi-join. Broadcasting a large side just to avoid a shuffle only trades one cost for executor-local comparison work.
7.1. Observed local 10M run
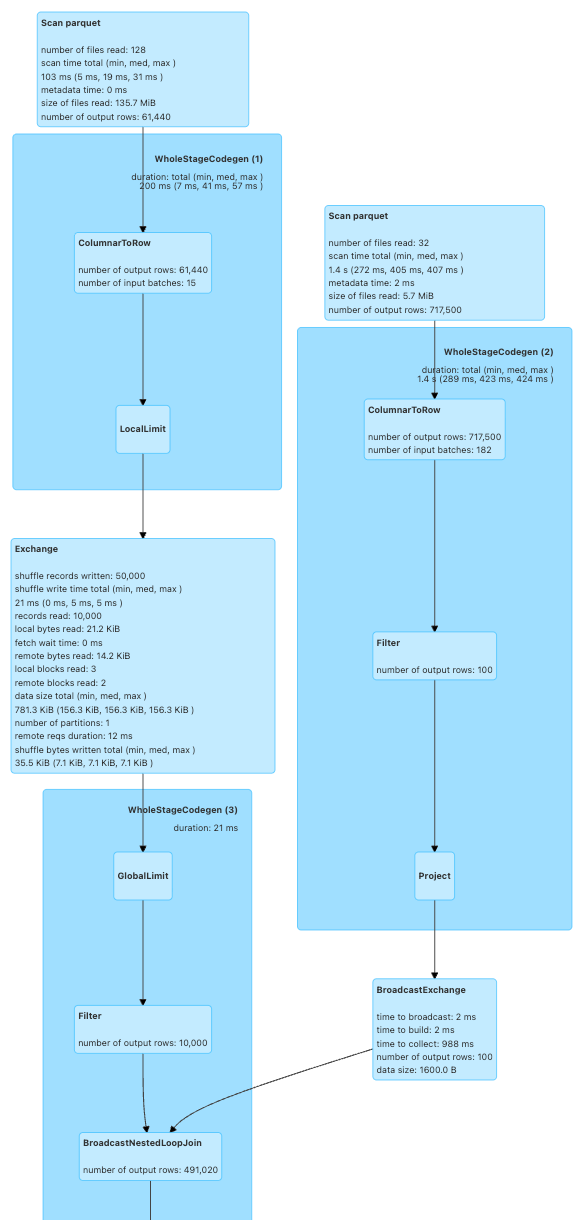
The Spark UI shows BroadcastNestedLoopJoin producing a 491,020-row result in
1.567 seconds. The right side filters the customer threshold table down to 100
rows, and BroadcastExchange turns it into a 1.6 KiB relation. The bounded
10,000-row fact side is compared against that relation using the non-equality
predicate; there is no hash lookup that could replace those comparisons.
8. Results from the local standalone cluster
8.1. 10M results
The table below aggregates metrics from every completed stage of each 10M run
in Spark History Server. Input is Spark’s reported inputBytes; shuffle read
and write include the small final count() aggregation stage. Max stage is
the longest stage wall-clock duration, rounded to whole seconds.
| Strategy | Observed operator | Result rows | Action elapsed | Max stage | Input | Shuffle read / write | Memory / disk spill |
|---|---|---|---|---|---|---|---|
| Broadcast Hash | BroadcastHashJoin |
10M | 1.493 s | 1 s | 26.1 MiB | 295 B / 295 B | 0 B / 0 B |
| Shuffle Hash | ShuffledHashJoin |
10M | 2.826 s | 1 s | 26.1 MiB | 3.8 MiB / 3.8 MiB | 0 B / 0 B |
| Sort-Merge | SortMergeJoin |
10M | 3.467 s | 2 s | 26.1 MiB | 3.8 MiB / 3.8 MiB | 0 B / 0 B |
On this dataset Broadcast Hash Join is fastest, because the 10K-product side is
cheap to copy and the equality-join shuffle is skipped entirely. Shuffle Hash
and Sort-Merge move the same inputs by product_id; Sort-Merge then also sorts
them.
| Strategy | Observed operator | Result rows | Action elapsed | Max stage | Input | Shuffle read / write | Memory / disk spill |
|---|---|---|---|---|---|---|---|
| Cartesian | CartesianProduct |
1M | 1.094 s | 1 s | 55.3 KiB | 59 B / 1.4 KiB | 0 B / 0 B |
| Broadcast Nested Loop | BroadcastNestedLoopJoin |
491,020 | 1.567 s | 1 s | 5.4 MiB | 0 B / 35.5 KiB | 0 B / 0 B |
These two rows use limited inputs and different predicates: Cartesian creates 10,000 × 100 pairs, while Broadcast Nested Loop compares 10,000 fact rows with 100 broadcast threshold rows. Their timings only illustrate the bounded lab workloads and should not be compared with the equality-join numbers.
8.2. 100M results: three runs per equality strategy
These runs use the same 100M fact and 10K products inputs on the local
standalone cluster. Each strategy ran three times, every run returned 100M rows,
and the saved plan showed the expected operator. The stage metrics are History
Server totals for one representative completed run, and the shuffle totals
include the tiny final count() aggregation.
| Strategy | Observed operator | Action elapsed, runs 1 / 2 / 3 | Median action elapsed | Stage input | Shuffle read / write | Memory / disk spill |
|---|---|---|---|---|---|---|
| Broadcast Hash | BroadcastHashJoin |
2.448 s / 2.073 s / 1.884 s | 2.073 s | 201.3 MiB | 1.5 KiB / 1.5 KiB | 0 B / 0 B |
| Shuffle Hash | ShuffledHashJoin |
5.789 s / 5.577 s / 5.517 s | 5.577 s | 201.3 MiB | 34.4 MiB / 34.4 MiB | 0 B / 0 B |
| Sort-Merge | SortMergeJoin |
6.700 s / 6.848 s / 6.848 s | 6.848 s | 201.3 MiB | 34.4 MiB / 34.4 MiB | 0 B / 0 B |
Across these three runs, Broadcast Hash Join again has the lowest median, since the 10K product relation is cheap to broadcast and the 100M fact side skips the equality-join shuffle. Shuffle Hash and Sort-Merge move the same shuffled data; Sort-Merge also sorts each partition, which accounts for its higher median here.
9. Run the companion lab locally
The companion lab contains the Docker Compose setup, data generation, strategy
commands, Spark UI URLs, evidence checklist, and cleanup instructions. For a
fair benchmark, compare Broadcast Hash, Shuffle Hash, and Sort-Merge on the
same fact and products inputs at one scale; the Cartesian and Broadcast
Nested Loop examples intentionally use bounded, different workloads.